📊 Expand Model Config
  Spark-X2.6-4B-bf16:
    cmd: >
      vllm serve /models/spark-x2.6/bf16
      --served-model-name Spark-X2.6-4B-bf16
      --port ${PORT}
      --max-model-len 131072
      --max-num-seqs 1
      --gpu-memory-utilization 0.9
      --dtype bfloat16
      --enable-prefix-caching
      --async-scheduling
      --chat-template /models/spark-x2.6/bf16/chat_template.jinja
      --reasoning-parser qwen3
      --enable-auto-tool-choice
      --tool-call-parser spark25
  Spark-X2.6-4B-fp8:
    cmd: >
      vllm serve /models/spark-x2.6/fp8
      --served-model-name Spark-X2.6-4B-fp8
      --port ${PORT}
      --max-model-len 131072
      --max-num-seqs 1
      --gpu-memory-utilization 0.9
      --dtype bfloat16
      --enable-prefix-caching
      --async-scheduling
      --chat-template /models/spark-x2.6/fp8/chat_template.jinja
      --reasoning-parser qwen3
      --enable-auto-tool-choice
      --tool-call-parser spark25
  Spark-X2.6-4B-Q8:
    cmd: >
      /usr/local/bin/llama-server
      --port ${PORT}
      --model /models/spark-x2.6/Spark-X2.6-4B-Q8_0.gguf
      --ctx-size 131072
      -ngl 99
      --main-gpu 0
      --split-mode none
      --fit off
      --flash-attn on
      --temp 1.0 --top-p 0.95 --top-k 0
      --jinja
      --parallel 1
      --batch-size 4096
      --ubatch-size 2048
  Spark-X2.6-4B-Q4_K_M:
    cmd: >
      /usr/local/bin/llama-server
      --port ${PORT}
      --model /models/spark-x2.6/Spark-X2.6-4B-Q4_K_M.gguf
      --ctx-size 131072
      -ngl 99
      --main-gpu 0
      --split-mode none
      --fit off
      --flash-attn on
      --temp 1.0 --top-p 0.95 --top-k 0
      --jinja
      --parallel 1
      --batch-size 4096
      --ubatch-size 2048
Intro
Back in my Small LLM Finale entry I setled on Nanbeige4.2-3B as my go-to small model. XHToken’s Spark-X2.5-4B was close behind, so when I saw they dropped the sequel (Spark-X2.6-4B) with notably better benchmarks I had to pull it and give it a try. I ran it through the same tests as the models in that previous entry, and a little bit more. I wanted to be able to compare to the results there but also experiment a bit with different quantizations. I ended up focusing on BF16, FP8, Q8_0.gguf, and Q4_K_M.gguf.
Lets find out if 2.6 is enough better than 2.5 to consider using over Nanbeige.
Speed
Prefill / Decode Sweep
Single stream synthetic sweep for a quick speed check. 512 tokens generated, prompt size walked from 1k up to max. The two vLLM quants were served at the model’s full --max-model-len 1048576 for this one, so they run all the way out to 1m. The GGUF quants were served at --ctx-size 131072 like the config block above, so their lines stop at 131k.
📊 Expand Speed Table
Each cell is prefill tok/s · time-to-first-token · decode tok/s at that context size:
| Context | BF16 (vLLM) | FP8 (vLLM) | Q8_0 (llama.cpp) | Q4_K_M (llama.cpp) |
|---|---|---|---|---|
| 1k | 27,155 · 0.04 s · 147.7 | 41,067 · 0.02 s · 214.0 | 11,038 · 0.09 s · 196.7 | 11,032 · 0.09 s · 240.6 |
| 8k | 37,662 · 0.19 s · 144.6 | 53,430 · 0.14 s · 207.4 | 18,346 · 0.40 s · 188.8 | 17,799 · 0.41 s · 222.4 |
| 32k | 31,339 · 0.91 s · 135.3 | 41,715 · 0.69 s · 188.4 | 19,018 · 1.51 s · 169.6 | 18,563 · 1.54 s · 202.5 |
| 131k | 18,794 · 6.07 s · 105.5 | 22,221 · 5.13 s · 134.4 | 11,863 · 9.63 s · 125.0 | 11,696 · 9.76 s · 143.9 |
| 262k | 12,032 · 18.96 s · 83.2 | 13,450 · 16.96 s · 100.0 | - | - |
| 524k | 6,924 · 65.86 s · 58.5 | 7,397 · 61.66 s · 66.3 | - | - |
| 1M | 4,036 · 215.45 s · 38.1 | 4,076 · 213.36 s · 41.3 | - | - |
| mean (1k-131k) | 28,738 · 1.80 s · 133.3 | 39,608 · 1.49 s · 186.0 | 15,066 · 2.91 s · 170.0 | 14,772 · 2.95 s · 202.3 |
Prompt tokens were 1,005 / 7,238 / 28,608 / 114,090 / 228,066 / 456,017 / 869,679 - the harness leaves headroom above the prompt for the 512 generated tokens. The 1M BF16 point is a single rep, the 1M FP8 point is two.
llama.cpp also reports a server-side prefill number (15.7k at 1k prompt, 21.8k / 21.7k at 8k / 32k, 12.7k at 131k). I used the client-measured column for all four so the columns are comparable - at 131k the two agree to within 7%, at 8k they don’t.
Decode order never changes. Smaller quant, faster decode on a single stream nearly context-independent.
FP8’s prefill lead evaporates as the prompt grows but 33%+ at 32k or less is HUGE for the range I’ll actually use this model for. 1 million ctx is just fun to see.
llama.cpp prefill tops out near 19k. Falls behind vLLM as always. Q4_K_M does have the small decode lead, but sacrifices TTFT for it.
Worth noting as always: vLLM took 23.5 s / 23.4 s to load and warm up versus 1.5 s for both GGUFs. If this is an always-loaded task model, no big deal, but llama.cpp makes a load-on-demand setup viable.
Concurrency
1,2,4,8 simultaneous requests. vLLM gets to shine as it always does.
📊 Expand Concurrency Tables
Table one is the per-client experience - each cell is aggregate prefill tok/s · mean TTFT (worst TTFT) · per-client decode tok/s at that client count:
| Clients | BF16 (vLLM) | FP8 (vLLM) | Q8_0 (llama.cpp) | Q4_K_M (llama.cpp) |
|---|---|---|---|---|
| 1 | 37,449 · 0.19 (0.19) s · 147.9 | 53,629 · 0.13 (0.13) s · 214.3 | 18,376 · 0.39 (0.39) s · 197.0 | 17,887 · 0.41 (0.41) s · 225.7 |
| 2 | 39,648 · 0.28 (0.37) s · 139.6 | 56,299 · 0.20 (0.26) s · 199.3 | 20,133 · 0.66 (0.72) s · 152.2 | 19,492 · 0.68 (0.74) s · 104.9 |
| 4 | 39,649 · 0.47 (0.73) s · 138.5 | 57,340 · 0.34 (0.51) s · 198.1 | 20,375 · 1.17 (1.42) s · 101.6 | 19,607 · 1.22 (1.48) s · 79.6 |
| 8 | 39,687 · 0.87 (1.46) s · 135.1 | 57,528 · 0.62 (1.01) s · 191.6 | 20,720 · 1.94 (2.79) s · 62.8 | 20,057 · 2.00 (2.89) s · 65.1 |
Table two is what the box as a whole puts out, aggregate decode tok/s, and how much of the theoretical 8x survived:
| Quant | 1 client | 2 | 4 | 8 | scaling 1 → 8 | per-client retained |
|---|---|---|---|---|---|---|
| BF16 (vLLM) | 147.9 | 278.8 | 550.8 | 1,064.5 | x7.20 | -8.6% |
| FP8 (vLLM) | 214.3 | 398.1 | 788.6 | 1,512.3 | x7.06 | -10.6% |
| Q8_0 (llama.cpp) | 197.0 | 304.2 | 406.3 | 501.6 | x2.55 | -68.1% |
| Q4_K_M (llama.cpp) | 225.7 | 209.7 | 318.3 | 520.3 | x2.31 | -71.2% |
vLLM barely notices the additional clients. Looking at the trend and my GPU’s utilization it would likely continue to scale favorably even up to 16 concurrent streams.
llama.cpp falls sharply. Q4_K_M even surprisingly had fewer aggregate decode tokens at concurency 2 than at 1.
Nothing surprising here, if you’re running a single user either is viable. If you’re expecting simultaneous requests, vLLM is your pick.
Size
All four context sizes:
| Quant | On disk | 16k ctx | 32k ctx | 64k ctx | 131k ctx | KV growth 16k → 131k |
|---|---|---|---|---|---|---|
| BF16 (vLLM) | 7.70 | 11.90 | 12.50 | 13.60 | 15.80 | +3.90 |
| FP8 (vLLM) | 4.20 | 8.40 | 9.00 | 10.10 | 12.31 | +3.91 |
| Q8_0 (llama.cpp) | 4.10 | 7.46 | 8.47 | 9.64 | 10.54 | +3.08 |
| Q4_K_M (llama.cpp) | 3.30 | 4.61 | 5.23 | 6.48 | 9.10 | +4.49 |
These numbers are simply for future reference. These would be slotted into a secondary GPU as a task model, so every gig counts. I’ll be weighing these numbers against the benchmark results heavily.
Traditional Benchmarks
note these are not comparable to leaderboards - different sample size, different Arena Hard judge.
All six typical suites, all four quants. These are the rerun numbers (28 Oct) - server default temperature rather than 0.0, 16k max tokens rather than 2048, and all four quants through one invocation at batch 10. The axis starts at 30 so the differences between quants are actually visible.
📊 Expand Benchmark Tables
Scores, as percentages:
| Suite | Samples | BF16 (vLLM) | FP8 (vLLM) | Q8_0 (llama.cpp) | Q4_K_M (llama.cpp) | Best |
|---|---|---|---|---|---|---|
| BFCL v4 | 300 | 85.00 | 83.00 | 81.33 | 81.33 | BF16 |
| IFEval (prompt-strict) | 250 | 74.40 | 76.40 | 81.60 | 76.80 | Q8_0 |
| MBPP+ | 378 | 78.04 | 76.46 | 79.37 | 75.13 | Q8_0 |
| MMLU-Pro | 420 | 61.67 | 61.91 | 61.43 | 60.24 | FP8 |
| Arena-Hard (winrate) | 75 | 58.80 | 56.40 | 55.04 | 46.28 | BF16 |
| HumanEval+ | 164 | 49.39 | 42.07 | 47.56 | 45.12 | BF16 |
| mean of the six | 67.88 | 66.04 | 67.72 | 64.15 | BF16 |
Difference against the BF16 run, in points:
| Suite | FP8 | Q8_0 | Q4_K_M |
|---|---|---|---|
| BFCL v4 | -2.00 | -3.67 | -3.67 |
| IFEval | +2.00 | +7.20 | +2.40 |
| MBPP+ | -1.58 | +1.33 | -2.91 |
| MMLU-Pro | +0.24 | -0.24 | -1.43 |
| Arena-Hard | -2.40 | -3.76 | -12.52 |
| HumanEval+ | -7.32 | -1.83 | -4.27 |
| mean | -1.84 | -0.16 | -3.73 |
IFEval’s other three variants (prompt-strict is what’s charted) - instruction-level strict 82.73 / 84.20 / 87.73 / 84.33, prompt-level loose 78.40 / 78.40 / 84.40 / 80.40, instruction-level loose 85.67 / 85.73 / 90.13 / 86.67.
BFCL v4 by subset, 50 samples each:
| Subset | BF16 | FP8 | Q8_0 | Q4_K_M |
|---|---|---|---|---|
| simple_python | 94 | 98 | 94 | 98 |
| multiple | 96 | 90 | 90 | 92 |
| parallel | 90 | 90 | 90 | 88 |
| irrelevance | 84 | 84 | 84 | 82 |
| live_multiple | 88 | 80 | 72 | 74 |
| multi_turn_base | 58 | 56 | 58 | 54 |
Mean wall time per request. The harness runs its own concurrency, so this mixes scheduling in with generation - same caveat as the last entry.
| Suite | BF16 | FP8 | Q8_0 | Q4_K_M |
|---|---|---|---|---|
| BFCL v4 | 1.89 s | 3.60 s | 5.94 s | 4.98 s |
| HumanEval+ | 3.45 s | 2.18 s | 4.44 s | 5.08 s |
| IFEval | 4.79 s | 2.42 s | 8.83 s | 8.46 s |
| MBPP+ | 7.34 s | 8.77 s | 23.38 s | 20.10 s |
| MMLU-Pro | 10.89 s | 8.77 s | 27.09 s | 23.63 s |
| Arena-Hard | 199.61 s | 195.31 s | 266.24 s | 240.75 s |
Instruction following went up with quantization. which is the opposite of expectation.
BFCL is still the flattest suite at a 3.7 point spread, but is directional by quant.
HumanEval+ is a pain cave for this model and the quantizations chip away at it further. We don’t have a clean directional result though.
Six-suite mean: BF16 67.88, Q8_0 67.72, FP8 66.04, Q4_K_M 64.15. Q4_K_M is the only quant that clearly had a reduction in capability (over 12 point drop in Arena-Hard!).
Pause… but some of these results are worse than Spark-X2.5-4B? I would have expected an outright beat.
| Suite | 2.5 | 2.6 |
|---|---|---|
| BFCL v4 | 82.33 | 85.00 |
| HumanEval+ | 74.39 | 49.39 |
| IFEval | 75.20 | 74.40 |
| MBPP+ | 83.07 | 78.04 |
| MMLU-Pro | 64.76 | 61.67 |
| Arena-Hard | 58.24 | 58.80 |
HumanEval+ was the only to fall by a statistically significant amount. MBPP is borderline and would need a much higher sample size to differentiate. The only take here is that 2.6 is meaningfully worse than 2.5 at no-think HumanEval+. It may be the case that 2.6 changed to rely heavier on thinking than 2.5 did, or somehow the test is broken. But to the best of my knowledge nothing has changed in the application of my benchmarks in the meantime. The in-harness tests will have to settle things.
Unstructured / Personal Tests
Curated suites need something to anchor them to reality. This is the same in-harness job I ran in the Small LLM Shootout and the Swift1.5 NVFP4 comparison, so these four quants line up directly against the models in those entries.
Open-WebUI Chat - Search, Reasoning, Function Calling
The same two-turn job:
- Can you find a few recently released unified memory systems with 128gb+ ram and compare their prices/availability/pros and cons?
- Can you format that information into a single page pdf so i can share it?
Same expectations as those entries: Nvidia RTX/DGX Spark, the Mx Ultra Mac Studios, the various Ryzen AI Max 395 mini pcs, MSRP, and pros/cons covering availability, memory size, bandwidth and compute. And of course it needs to find and call the PDF creation tool sitting in the harness.
Results
BF16 (vLLM · 7.7 GiB)
Open PDF ↗The only one of the four that used the task list - and it created, updated and closed every task cleanly, which is rare. Nine searches at the default N=5, prices all valid, though it never covered the M5 Ultra Studios. The report is formatted with no errors, and it is two pages, so the single page ask was ignored.
FP8 (vLLM · 4.2 GiB)
Open PDF ↗Seemingly the most research and the most results of any run here. It never touched the task tools and never deviated from N=5, but it worked really hard to respect the one page limit - checking and revising - and it actually shipped a single page.
Q8_0 (llama.cpp · 4.1 GiB)
Open PDF ↗No task list interaction at all, though it did adjust the search count on one call. Found few devices and the prices were inaccurate. The systems listed in the PDF differ greatly from the ones it told me about in chat.
Q4_K_M (llama.cpp · 3.3 GiB)
Researched better than Q8_0 - it actually found the expected systems and their prices - but still never opened a task, and it could not correctly form the tool call to create the PDF no matter how many times I retried. Nothing to show for it.
Only BF16 used the task list. It created the tasks, completed them, closed them and moved on - which is a legitimately rare level of sys prompt adherence. I have only seen this behavior done right a few times and only in much larger models. FP8, Q8_0 and Q4_K_M never opened one. All four still called the search tool without trouble.
Research quality did not track quant size. Q4_K_M found the expected systems and their prices better than Q8_0 did. And Q8_0’s chat answer listed different machines than its own PDF, which is a worse failure than simply being wrong once.
The one page ask is objectively checkable and only two of the four nailed it. BF16’s report is two pages while FP8 and Q8_0 are one. Notably, FP8 got there by actually looping to check and revise the layout. Very impressive.
Q4_K_M is the interesting failure of the group. It performed well BFCL but IRL it could not form one valid PDF tool call in as many attempts as I gave it. This is similar to Ninfer6000’s inability to form tool calls despite a notable victory in BFCL. Its calling into question the value of the BFCL suite.
Pelican on a Bicycle
And ending on the classic silly prompt, as always.
Generate an SVG of a pelican riding a bicycle
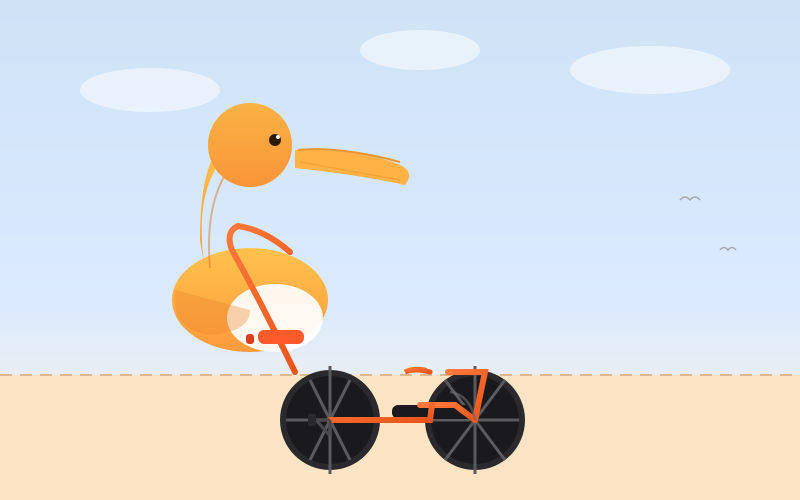
BF16 (vLLM · 7.7 GiB)
Open SVG ↗Not a very impressive pelican, but it competes with the best of this size class.
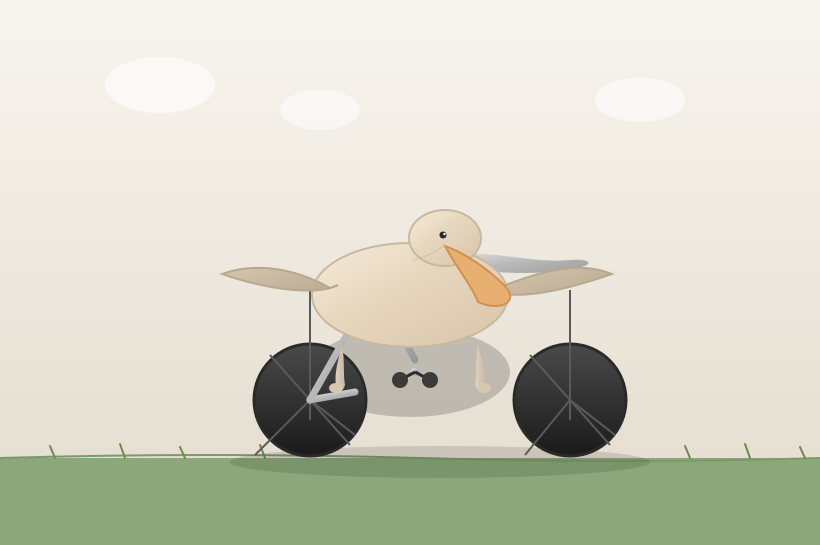
FP8 (vLLM · 4.2 GiB)
Open SVG ↗Similar quality to the BF16 run, unimpressive. Competitive for the size range, which is a low bar. Kinda looks like a sick drumset.
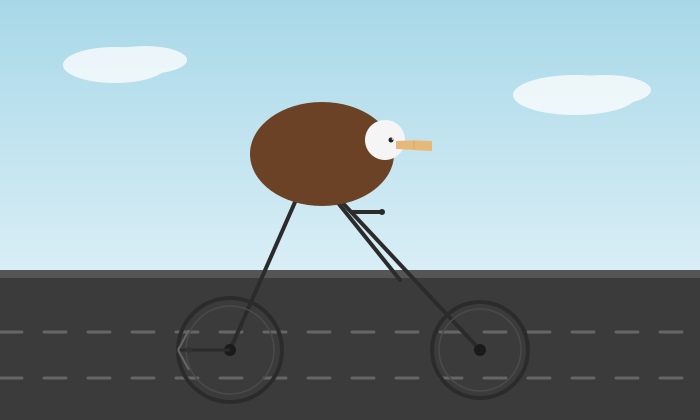
Q8_0 (llama.cpp · 4.1 GiB)
Open SVG ↗Awful. It literally made the body of a bird into a wheeled vehicle.
Q4_K_M (llama.cpp · 3.3 GiB)
Open SVG ↗As bad as the rest. At least there are wheels, but that's the extent of the praise.
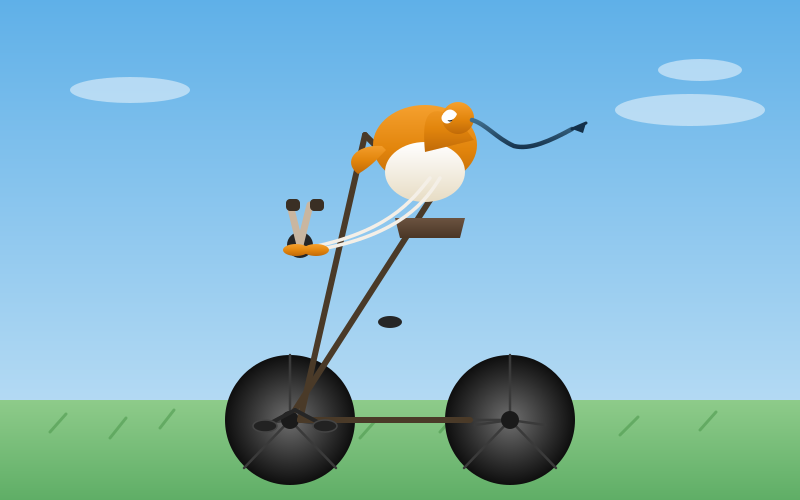
None of these are passing as a pelican on a bicycle to anyone. At least there are wheels. I would say that BF16’s result was actually mildly better than what Spark-X2.5-4b output in the roundup. Regardless, this one is still clearly out of reach for models this size. The quantization barely matters because none of them can draw a pelican.
Conclusion
tl;dr
Overall this model seems like its got a lot going for it in a vacuum, but doesn’t dethrone Nanbeige4.2-3b as my victor amongst the small models. It also doesn’t CLEARLY outrank the previous model in my tests of Spark-X2.5-4B. I’m unsure if there is something wrong with my setup or if the model changed in such a way that made the thinking being off a bigger hindrance.